HyperProbe | Resources
HyperProbe is an AI on-call agent that places read-only probes on running production code to capture exact variable state at the moment of failure, without a redeploy or restart.
Latest Articles
Insights, guides, and industry updates
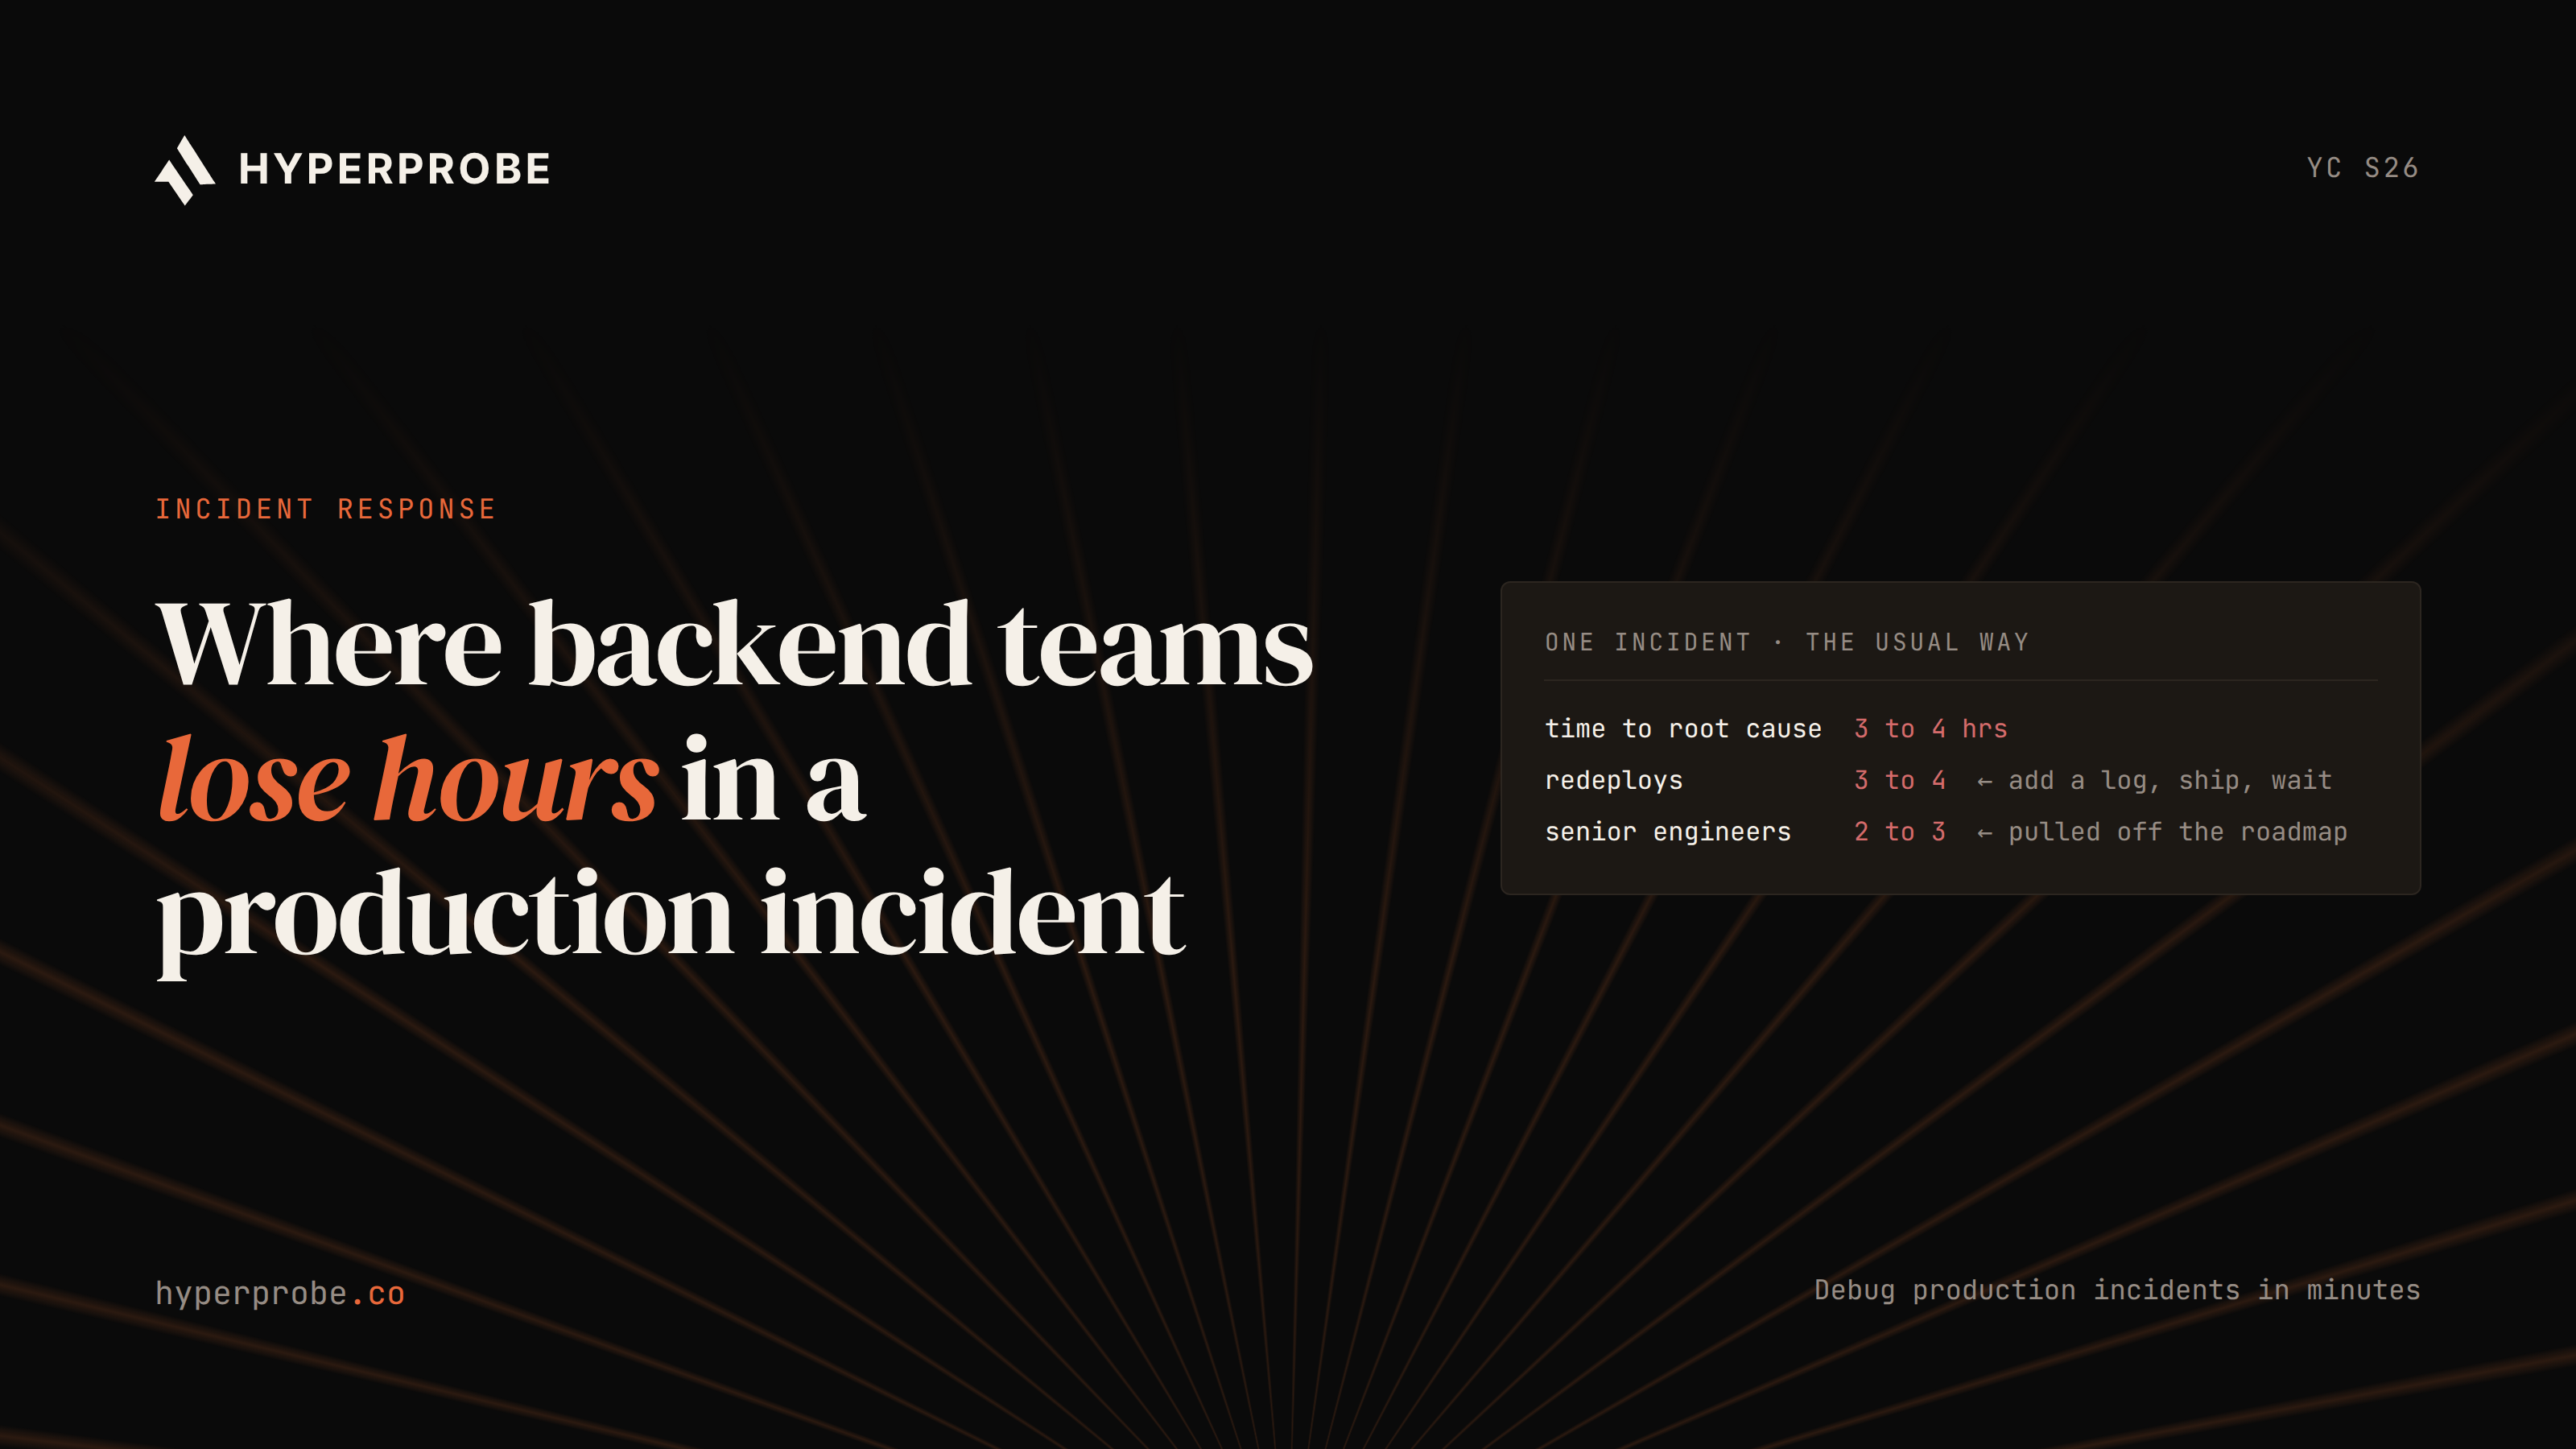
Where backend teams lose hours in a production incident
Mean time to resolution hides a lopsided split: detection is a tenth, investigation over half. See where backend incident hours go and how to audit yours.
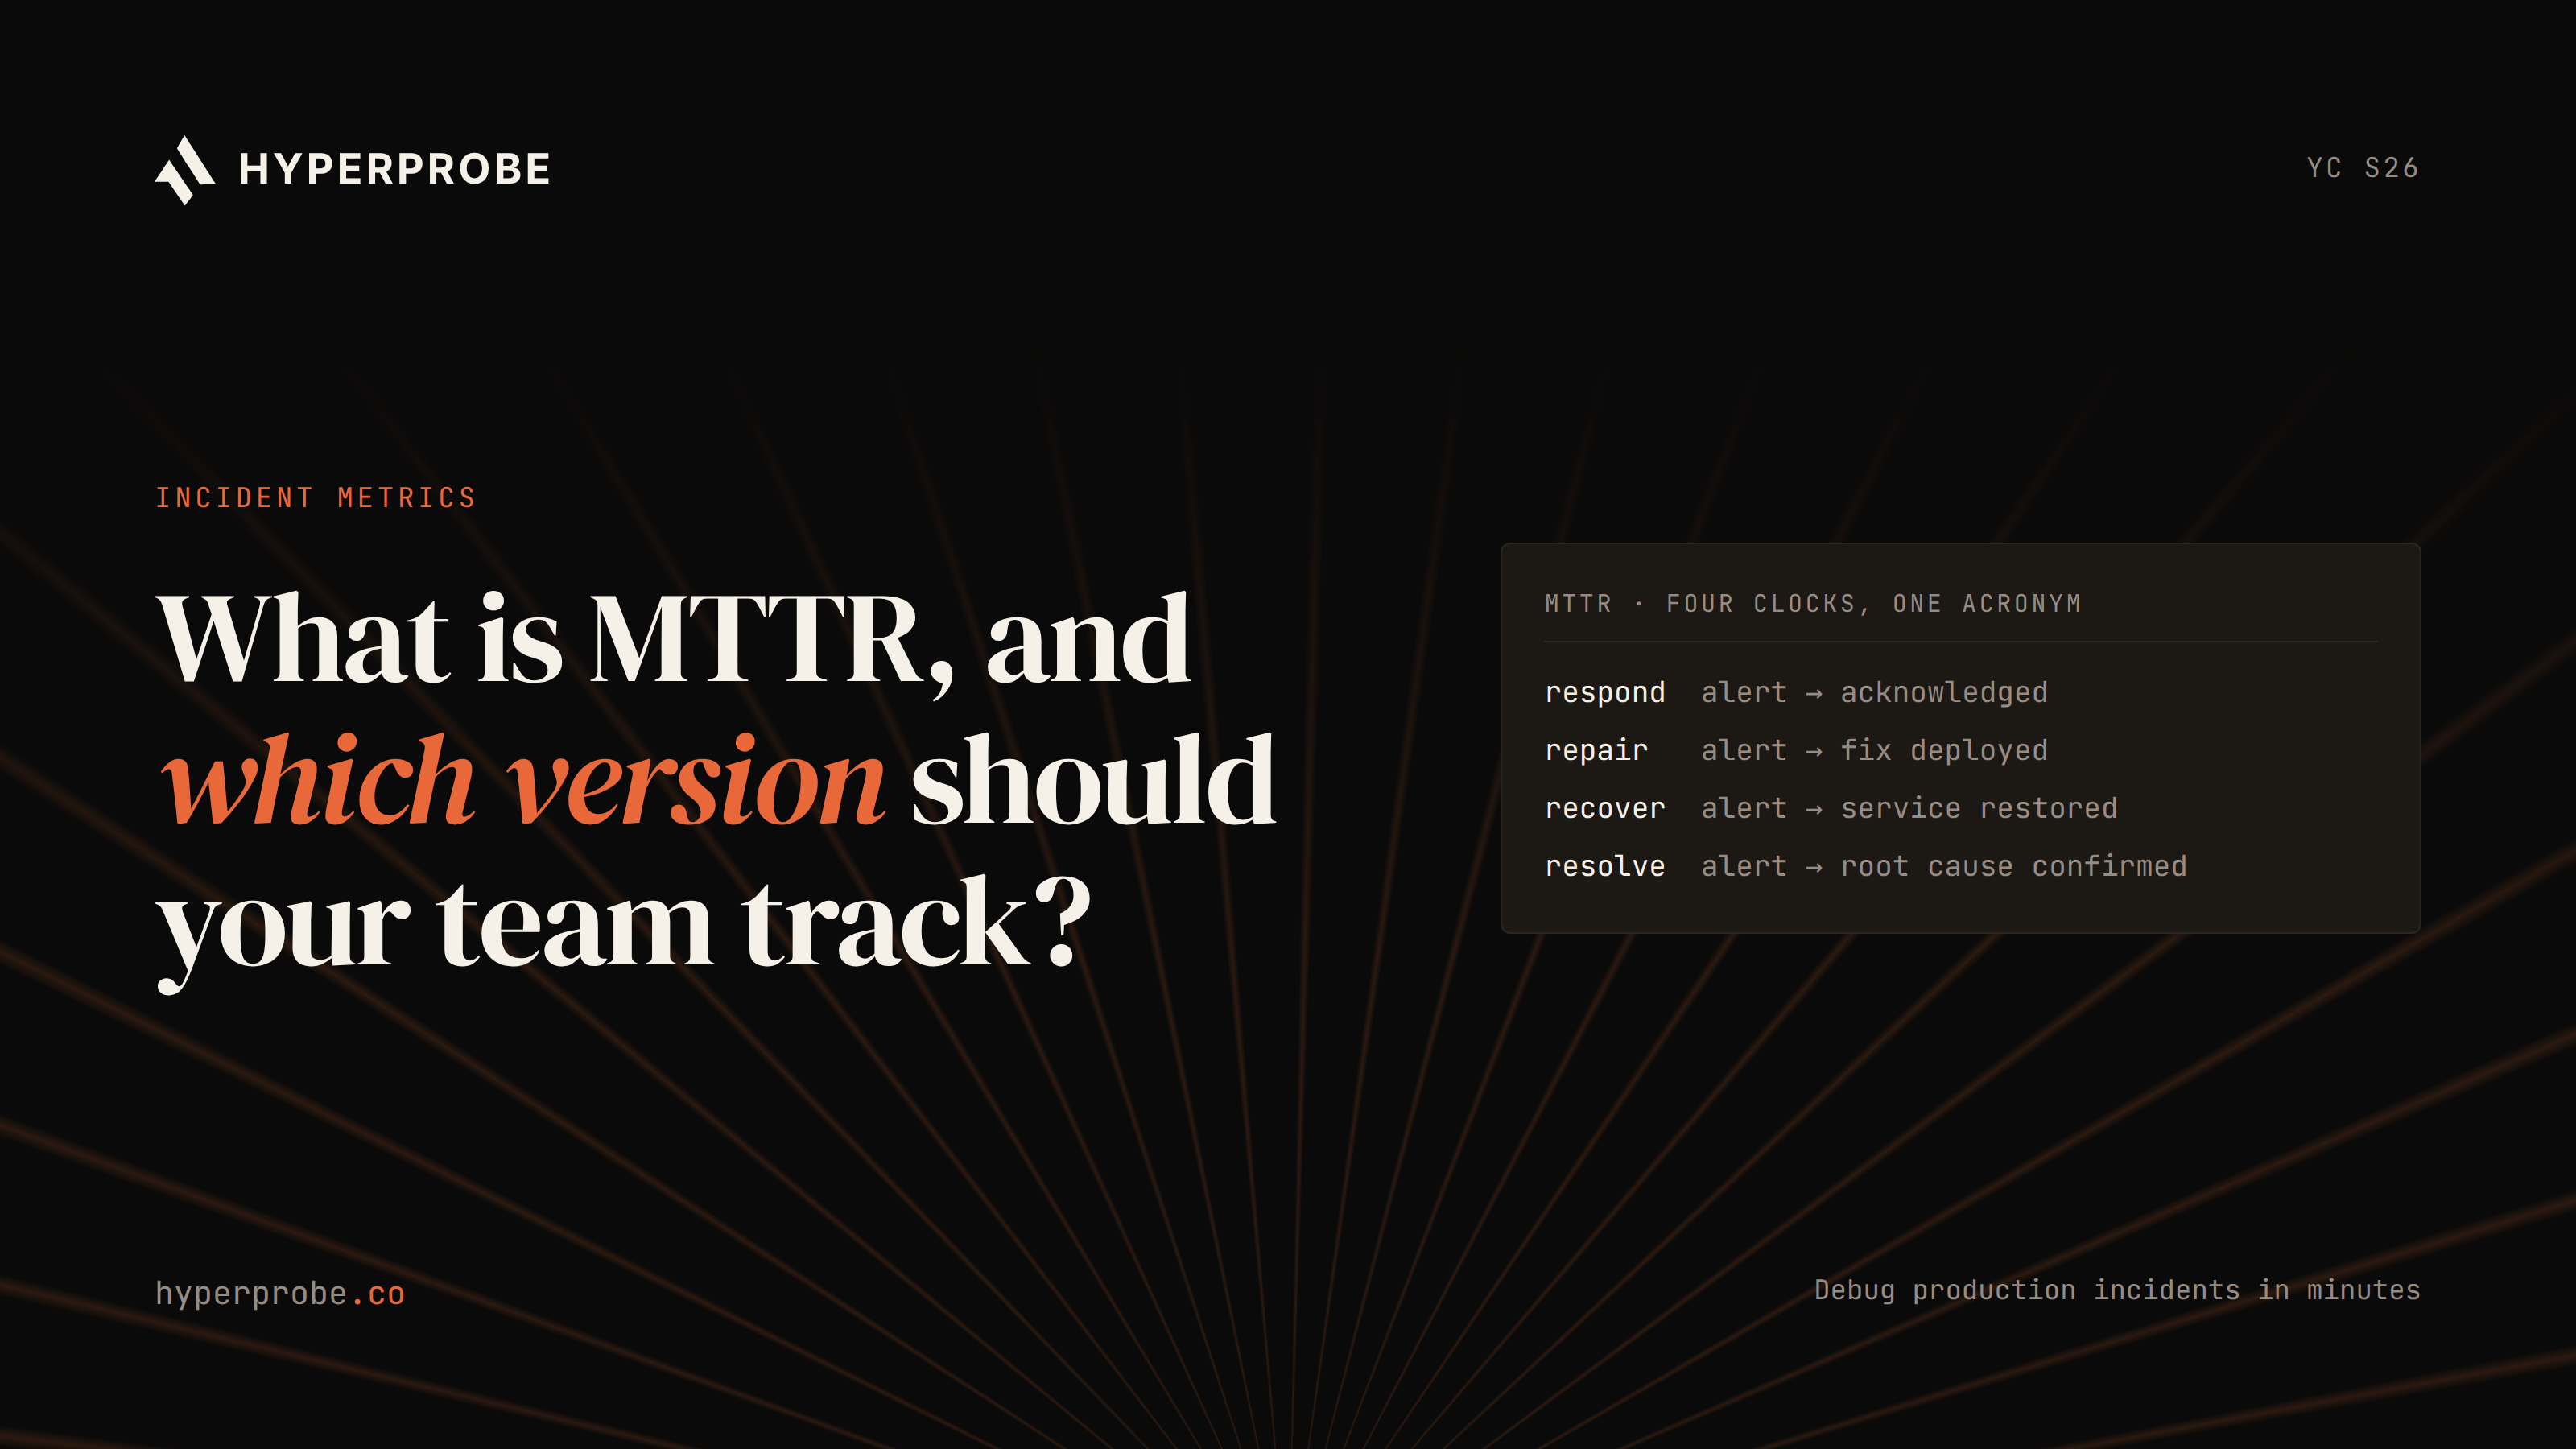
What is MTTR, and which version should your team track?
MTTR can mean repair, recovery, respond, or resolve. Learn what each version measures, how DORA redefined it, why the mean misleads, and which one your team should track.
 Shailendra SinghOct 23, 20268 min read
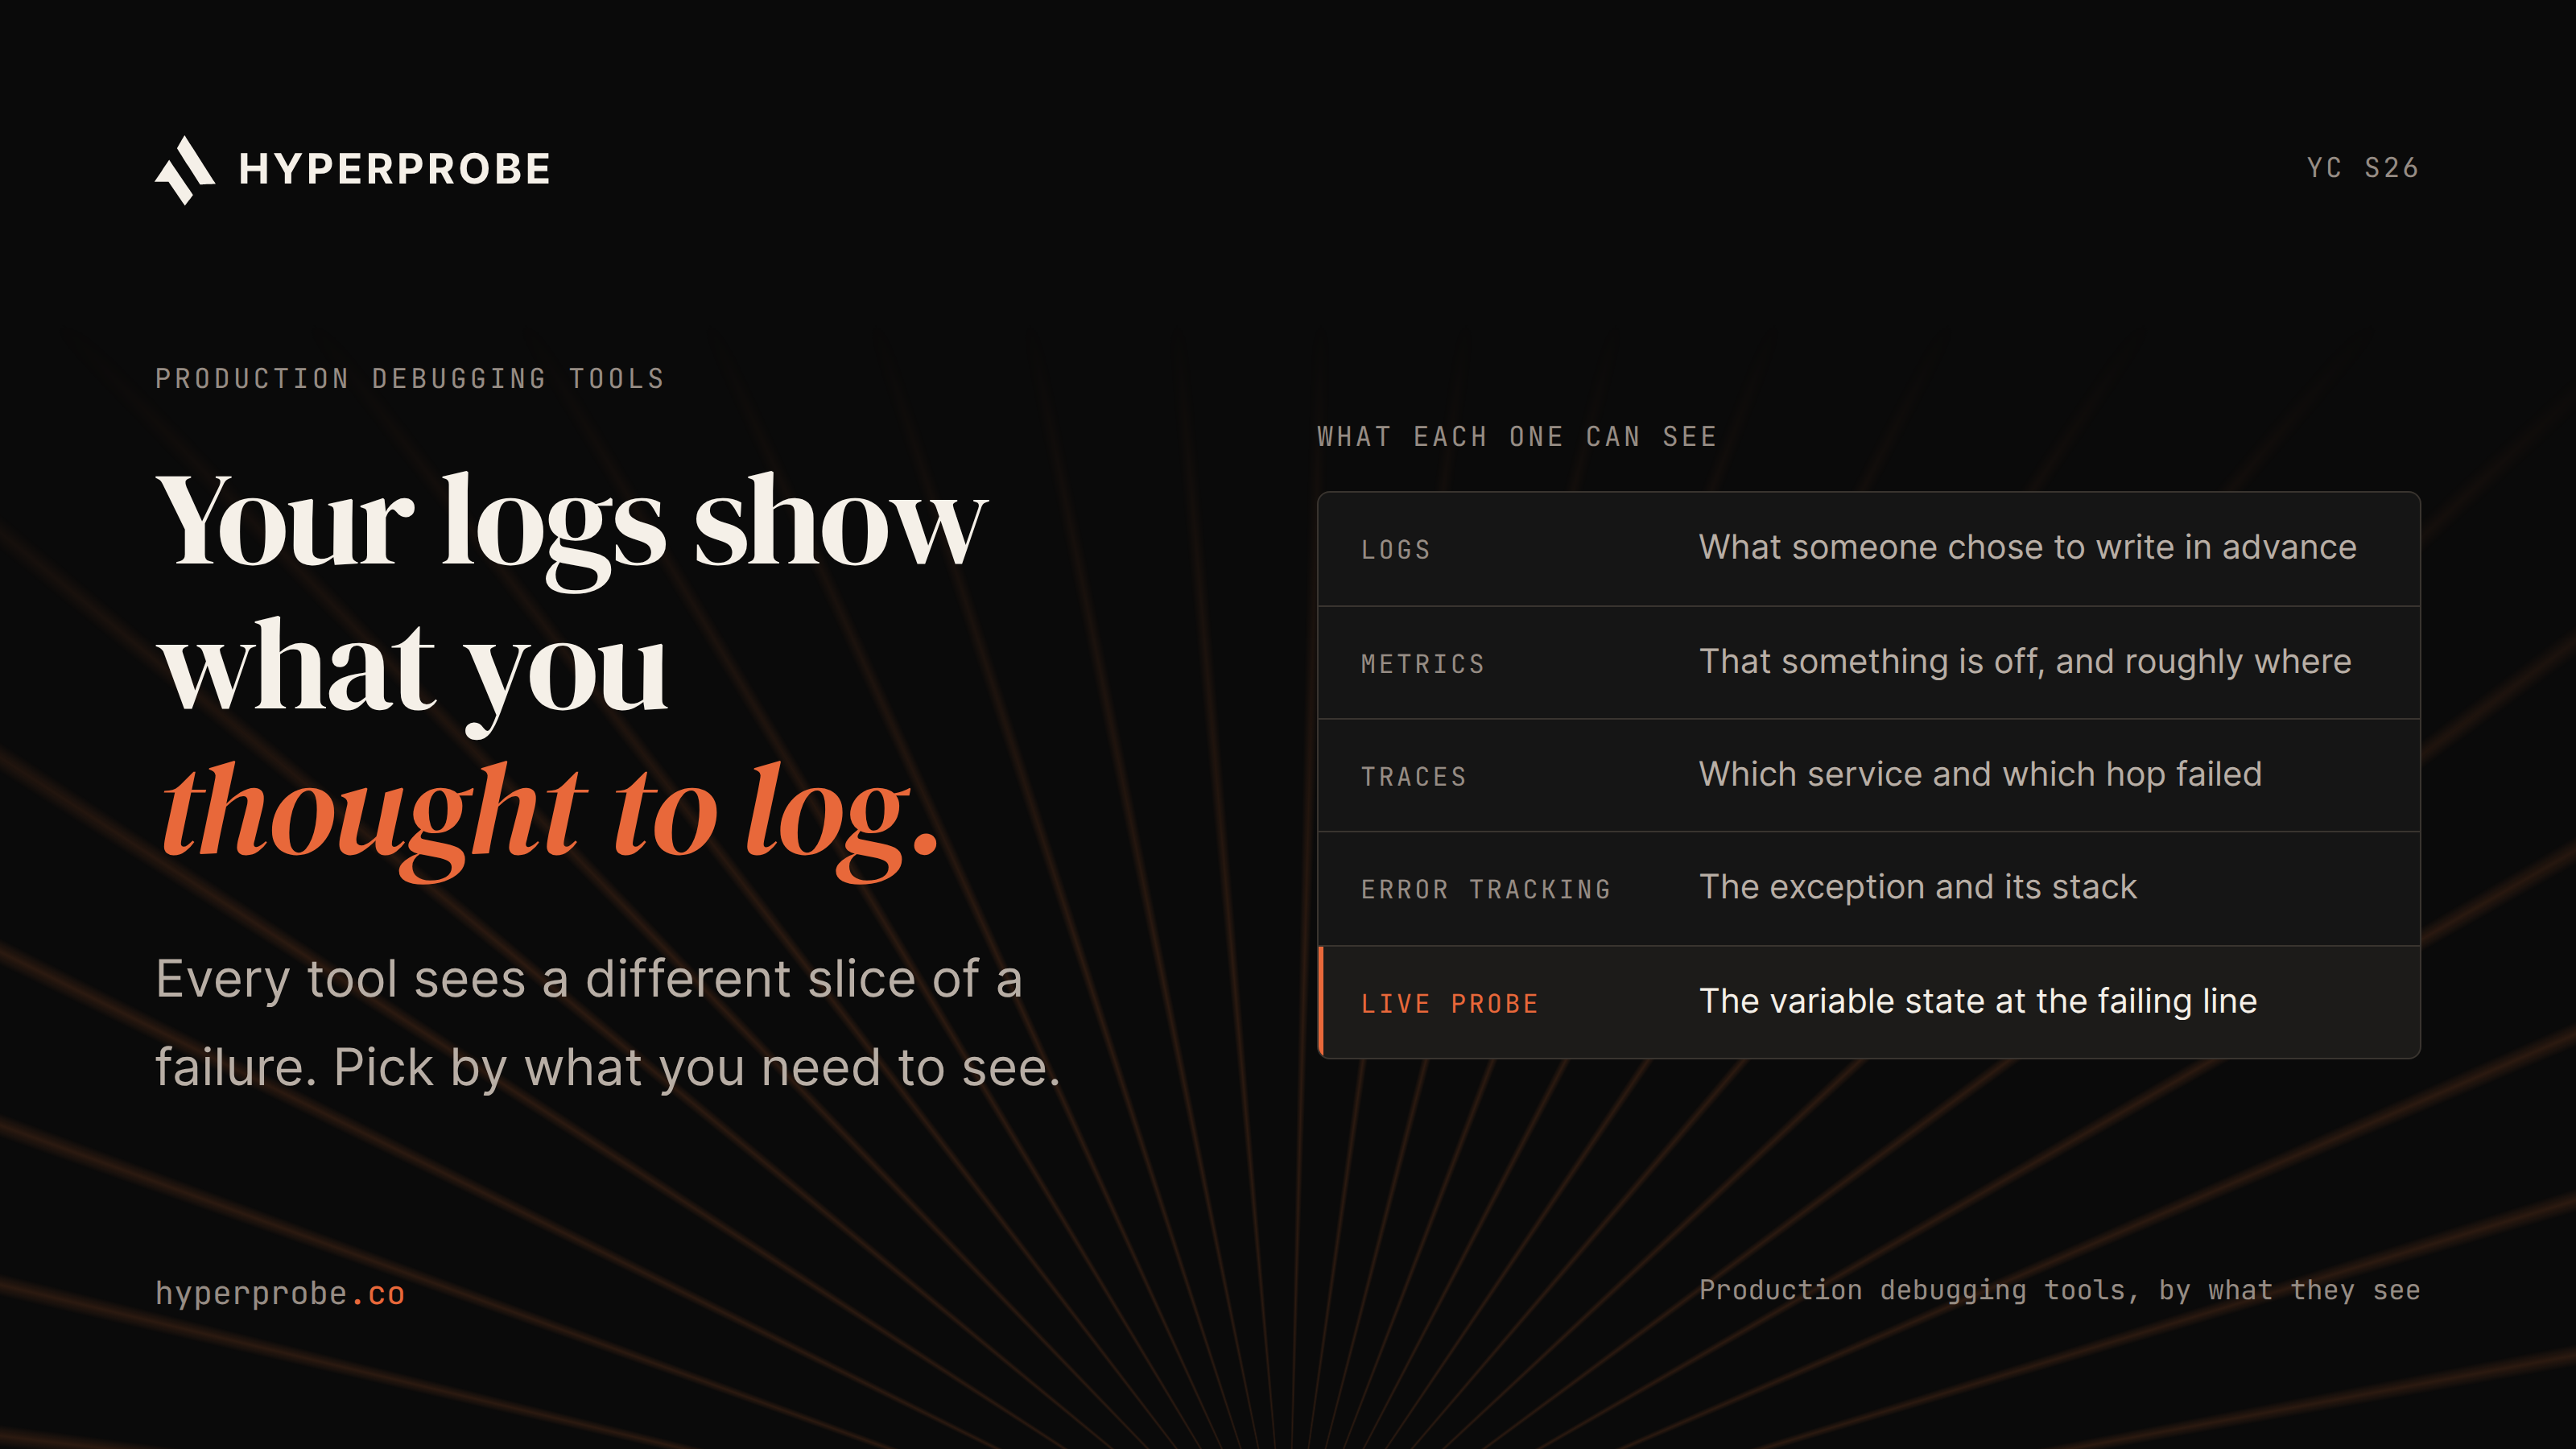
Best debugging tools for production, by what each one can see
Compare logs, APM, tracing, error tracking, profiling, debuggers and dynamic instrumentation by what each sees and misses in a production failure.
Shailendra SinghOct 22, 2026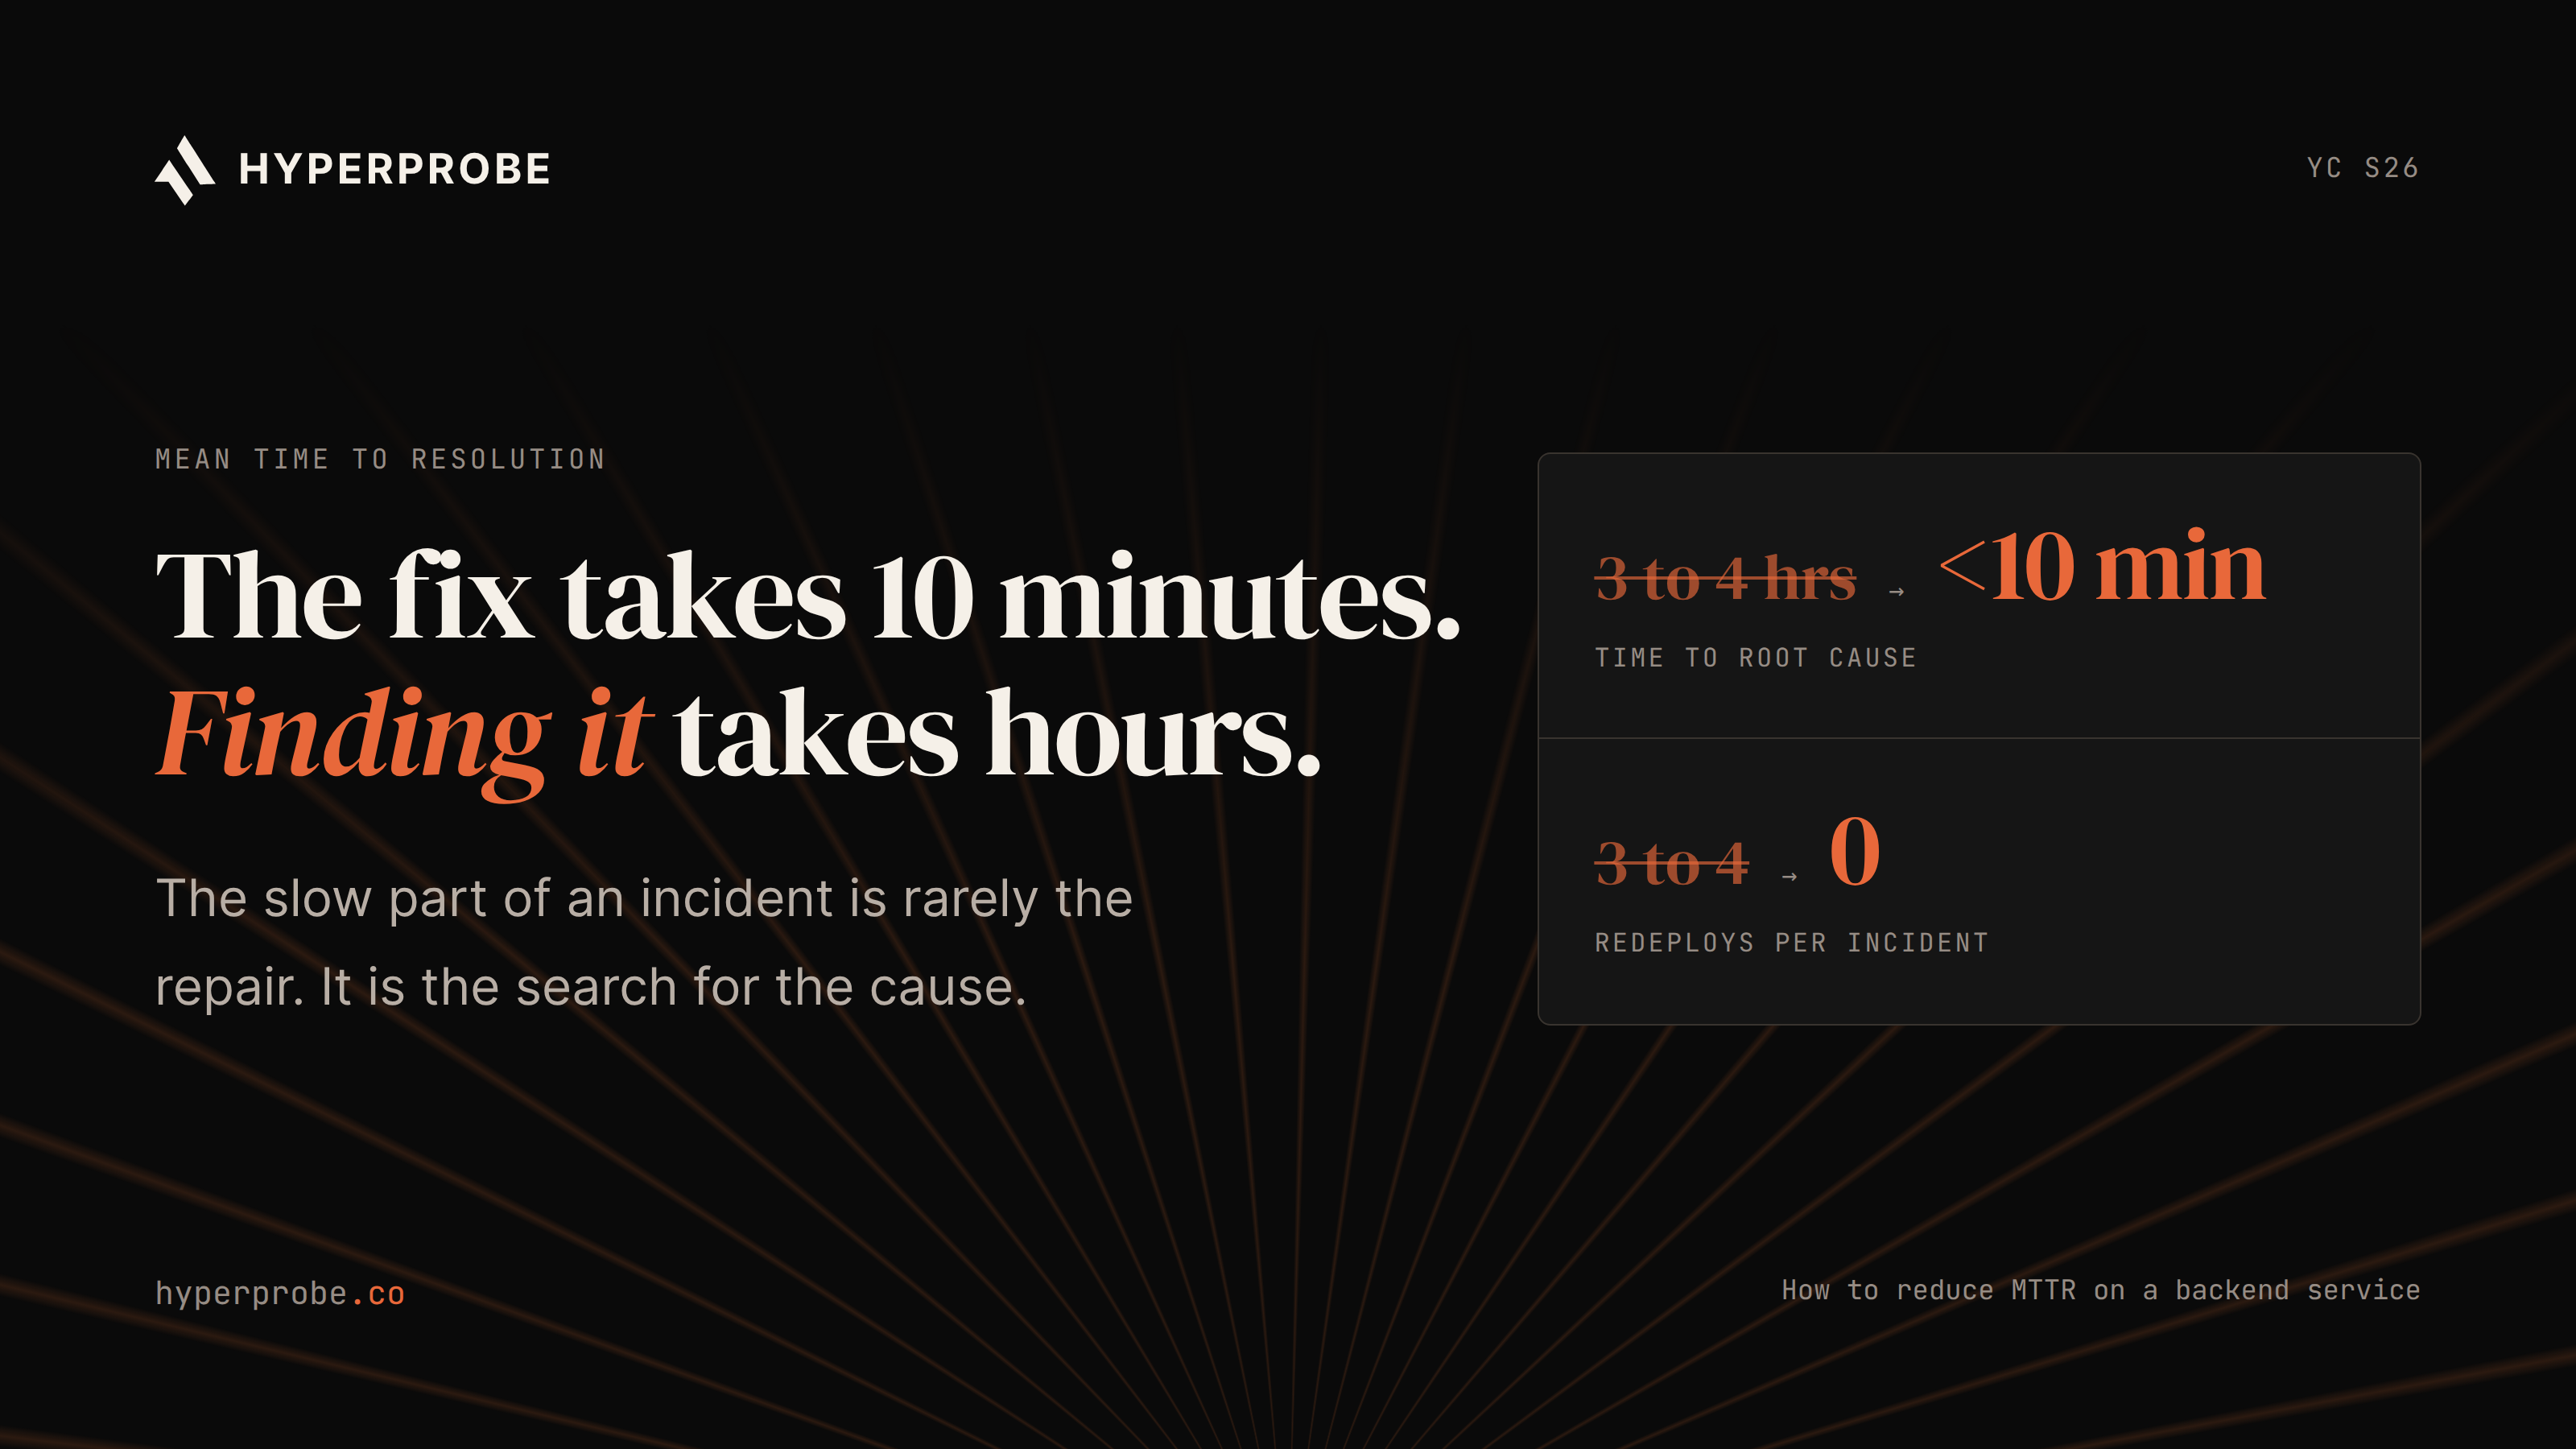
Runtime state and performance
How to Reduce Mean Time to Resolution on a Backend Service?
Learn how to reduce MTTR on a backend service by measuring diagnosis, avoiding information-only redeploys, and confirming root cause with evidence.
Shailendra SinghOct 21, 20268 min read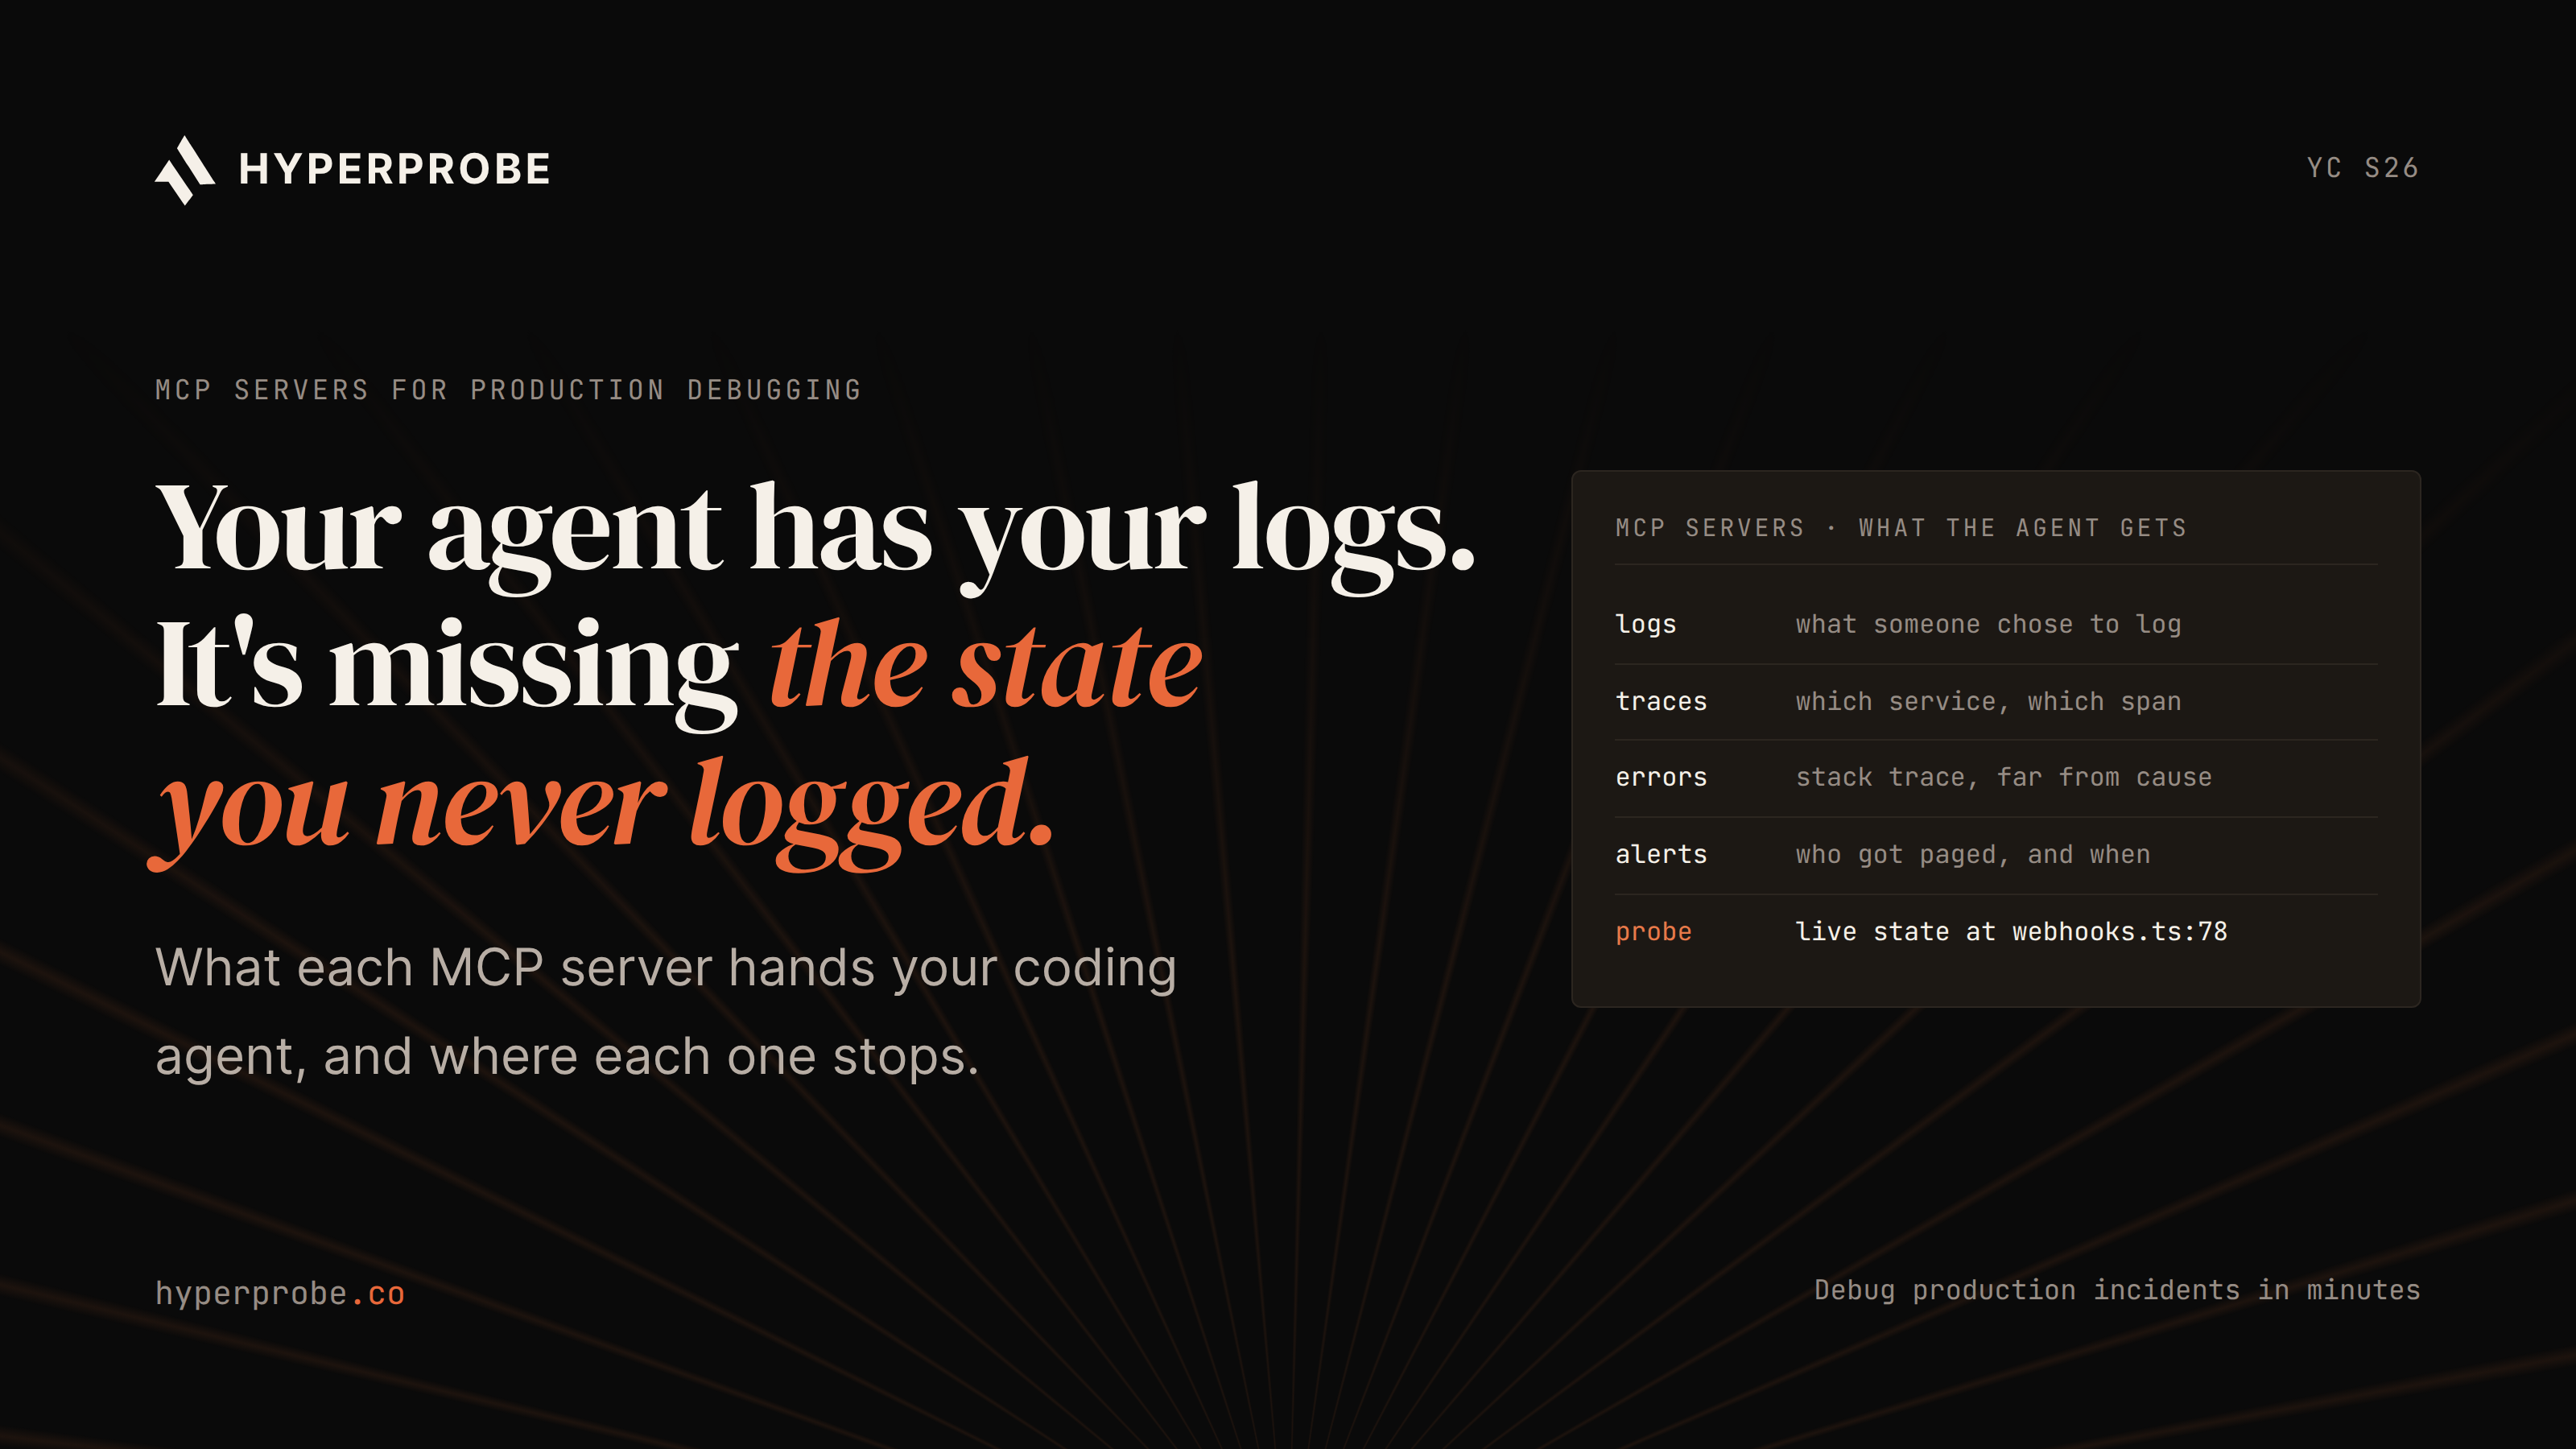
Production debugging and RCA
MCP servers for debugging production and what each gives an agent
Compare Claude Code MCP servers for production debugging, including Sentry, Datadog, PagerDuty, Honeycomb, Grafana, and debugger MCPs, plus their evidence gaps.
Shailendra SinghSep 20, 202610 min read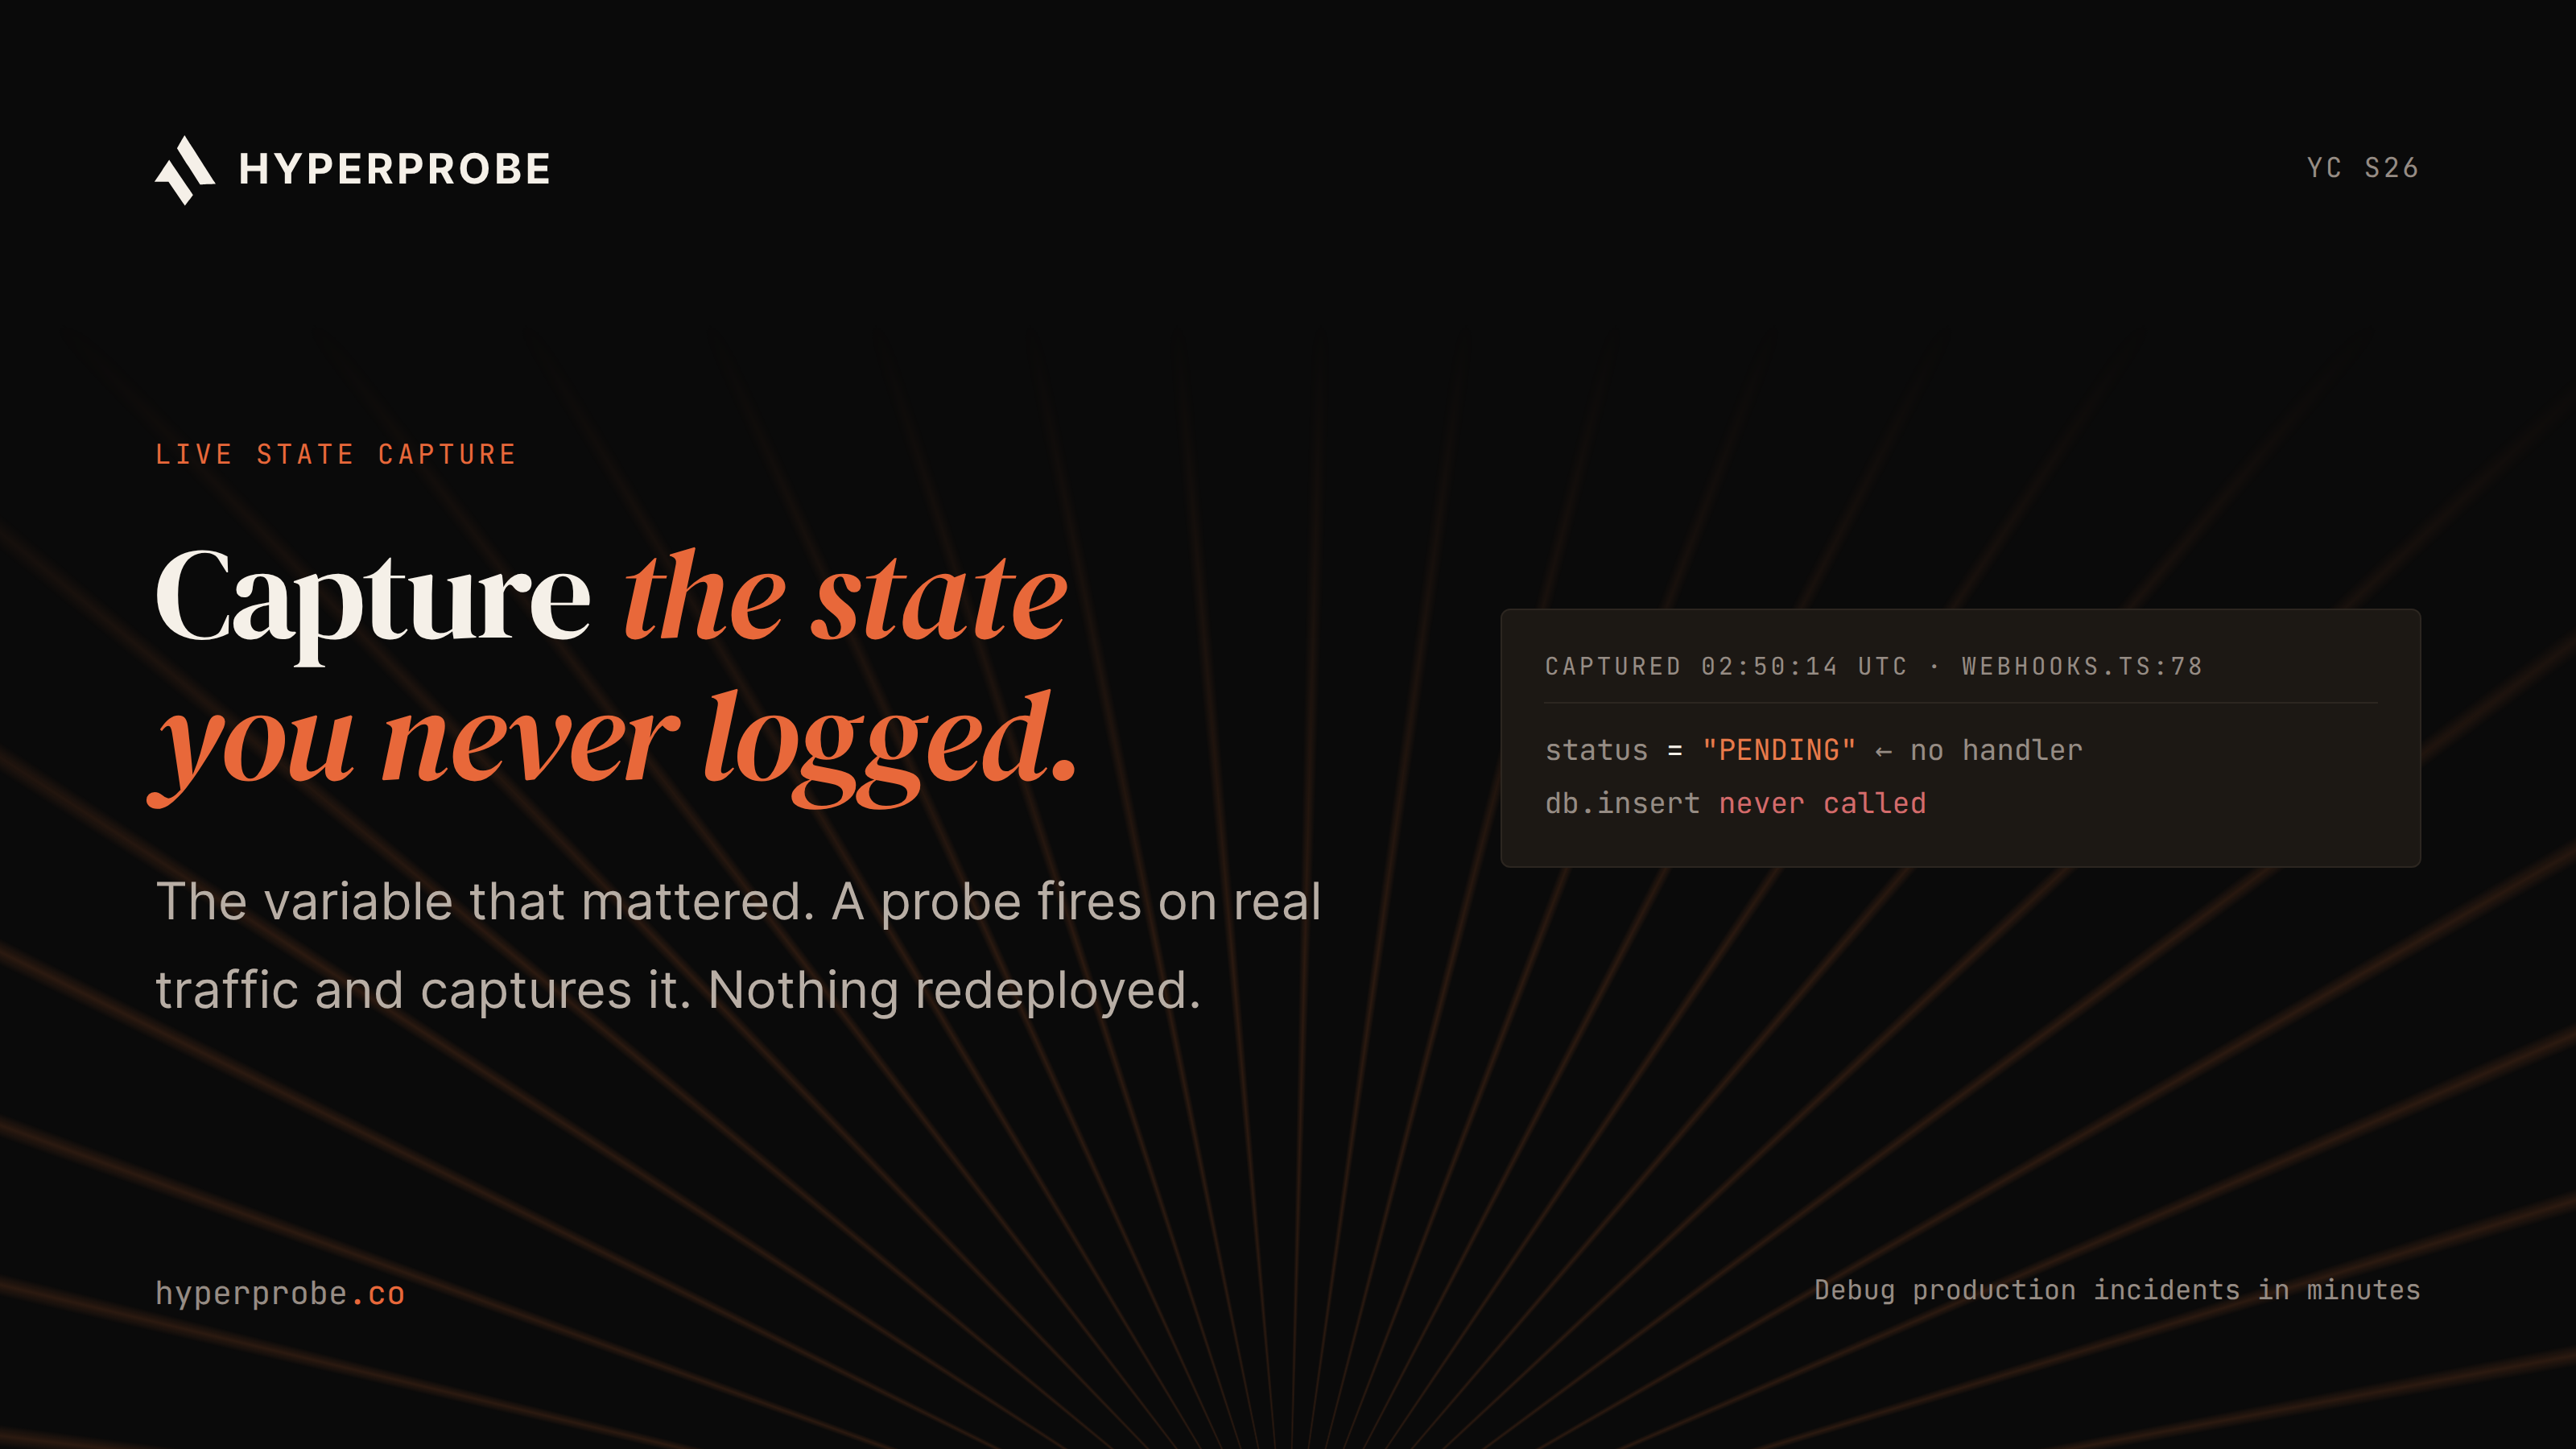
Production debugging and RCA
How to Capture a Variable That Was Never Logged
Learn how to capture variables in code when nothing was ever logged, from print statements and debuggers to production-safe dynamic instrumentation.
Shailendra SinghSep 16, 202610 min read